
Revised article
An Easy Way to Monitor a Website's Health
The problem
Recently the docker daemon running a wiki I host got into a bad state. My wiki ended up returning an HTTP error 403 for 3 days until I get poked by users.
To avoid such a situation in the future, I decided to look for an automated health check.
The solution
I found an easy and quick solution using the website healthchecks.io.
Choose an account and check schedule appropriate to the service you want to monitor.
I created an account and a job there. Got my ping URL!
After I wrote a script healthcheck.sh that I ended up running on the server hosting my wiki:
#!/bin/bash
set -eu

# Set this to the private ping URL from your Healthchecks account.
: "${HC_PING_URL:?Set HC_PING_URL before running this script}"
url="https://gameofroles.wiki/view/Accueil"

if status=$(curl --silent --show-error --output /dev/null \
    --write-out '%{http_code}' --connect-timeout 5 --max-time 15 "$url"); then
    if [ "$status" = "200" ]; then
        endpoint="$HC_PING_URL"
        message="Wiki up: HTTP $status"
    else
        endpoint="${HC_PING_URL%/}/fail"
        message="Wiki down: HTTP $status"
    fi
else
    endpoint="${HC_PING_URL%/}/fail"
    message="Wiki unreachable: connection or timeout error"
fi

curl --fail --silent --show-error --max-time 10 --retry 2 \
    --data-raw "$message" "$endpoint"
printf '%s\n' "$message"
The script checks for HTTP 200 and reports other responses or connection failures to /fail. Healthchecks numeric endpoints accept process exit statuses (0–255), not HTTP codes such as 403. The HTTP status is sent in the request body instead. See the ping API.
For a small site, this example runs every five minutes. Set the same schedule in Healthchecks and choose a grace period (for example, two minutes). Store HC_PING_URL in a private crontab environment entry before this line:
*/5 * * * * /wiki/healthcheck.sh
From now on, if my website is down, I will receive an automated email from healthchecks.io notifying me about the situation!
A failed HTTP check can be detected on the next run, up to roughly five minutes later, plus request and notification delays. If the whole server stops, the missing-ping alert depends on the configured schedule and grace period. A page returning 200 is not proof that every application feature is healthy; test a representative operation when needed.
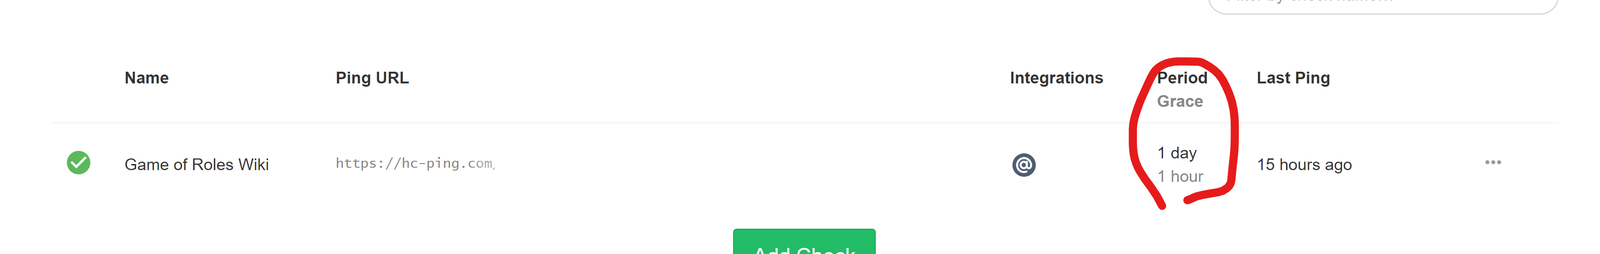
Photo by Hush Naidoo on Unsplash